30 July 2026
updated at: 3 August 2026
10 min
Someone buys a GPU server for an 8B-model chatbot, only to see the accelerator at 10% utilization in the monitoring tools. We’ll break down why two Xeon 6 processors with AMX are actually sufficient instead of a GPU, and what kind of machine this is.
A typical corporate AI project in 2026 looks like this: a knowledge base from PDFs, vector search, a chatbot built on top of an open 8B-parameter model, and 50 to 100 active users within the network perimeter. A server with an accelerator is purchased for this purpose because “AI is GPU.” A quarter later, the charts show that HBM is only 25% utilized, the SM cores are idle between requests, and half of the rack allocated to this project isn’t even running AI at all.
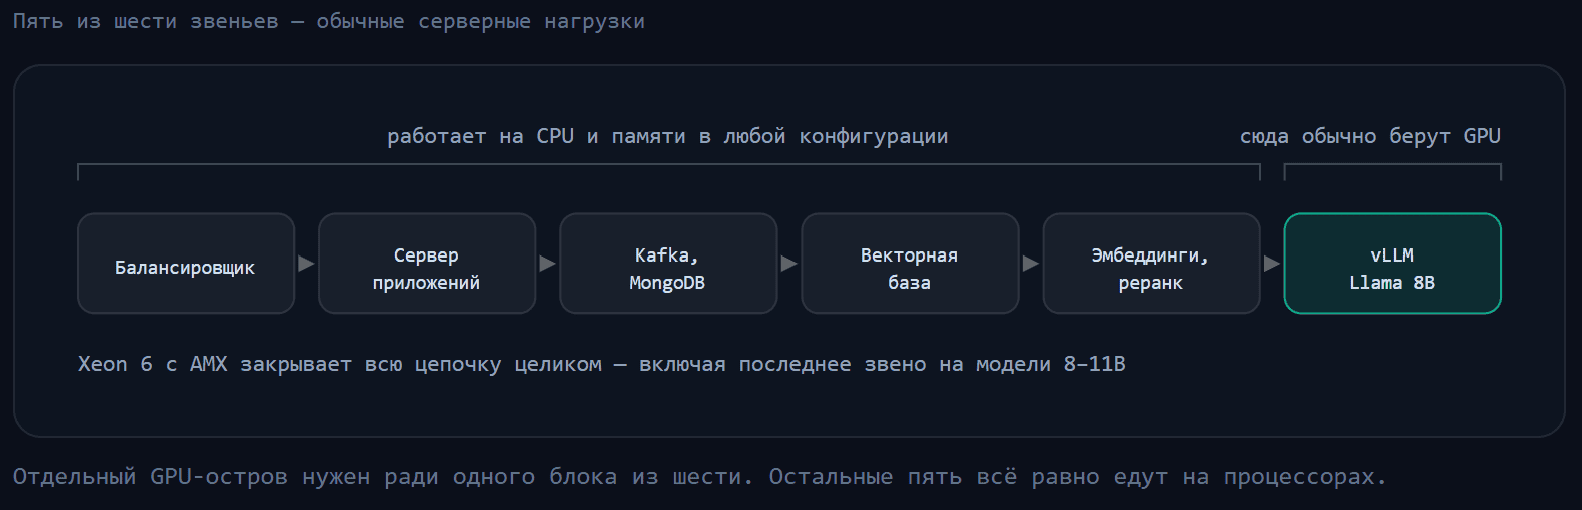
The second observation is more important than the first. The Retrieval-Augmented Generation (RAG) pipeline does not consist of a single model. It includes a load balancer, an application server, a Kafka queue, a vector database, MongoDB with metadata, an embedding model, a re-ranking model—and only at the very end, the vLLM engine with the LLM itself. Everything except the last component runs on the CPU and memory. If the LLM portion also fits within the CPU, the entire pipeline resides in a single cluster, on a single orchestrator, with a single operational model—instead of a “GPU island plus CPU infrastructure” setup.
What the RAG pipeline actually consists of
Third—data. Open models within your own environment eliminate information security concerns: documents, conversation logs, and tender correspondence never leave the data center, and instead of cloud credits for speech recognition APIs, you pay for the depreciation of your own hardware.
The Xeon 6 is divided into two lines: P-cores—performance per core—and E-cores—performance per watt (CDN, microservices, DevOps). P-cores are designed for machine learning and HPC.
Within the P-line, there is also a further division. The 6900P series (Granite Rapids AP) features up to 128 cores, 12 memory channels, and a thermal envelope of up to 500 W. The 6700P series (Granite Rapids SP) features up to 86 cores, 8 memory channels, a thermal envelope of up to 350 W, up to 88 PCIe 5.0 lanes, and up to 4 TB of memory per socket. The ITPOD-SL201-D12R-NV-G5 is built specifically for the SP profile: two sockets, up to 350 W per processor, and 32 DDR5 slots.
A key feature for inference is Intel AMX, a matrix accelerator built into the processor. It does not take resources away from the cores but functions as a built-in accelerator and supports FP16. Public benchmark results from Phoronix: the geometric mean across the entire test suite is 156.99 seconds with AMX enabled versus 57.15 seconds with it disabled. In other words, the difference between “inference on the CPU doesn’t take off” and “inference on the CPU works” isn’t down to the hardware generation, but rather a single block within the processor and a properly built engine.
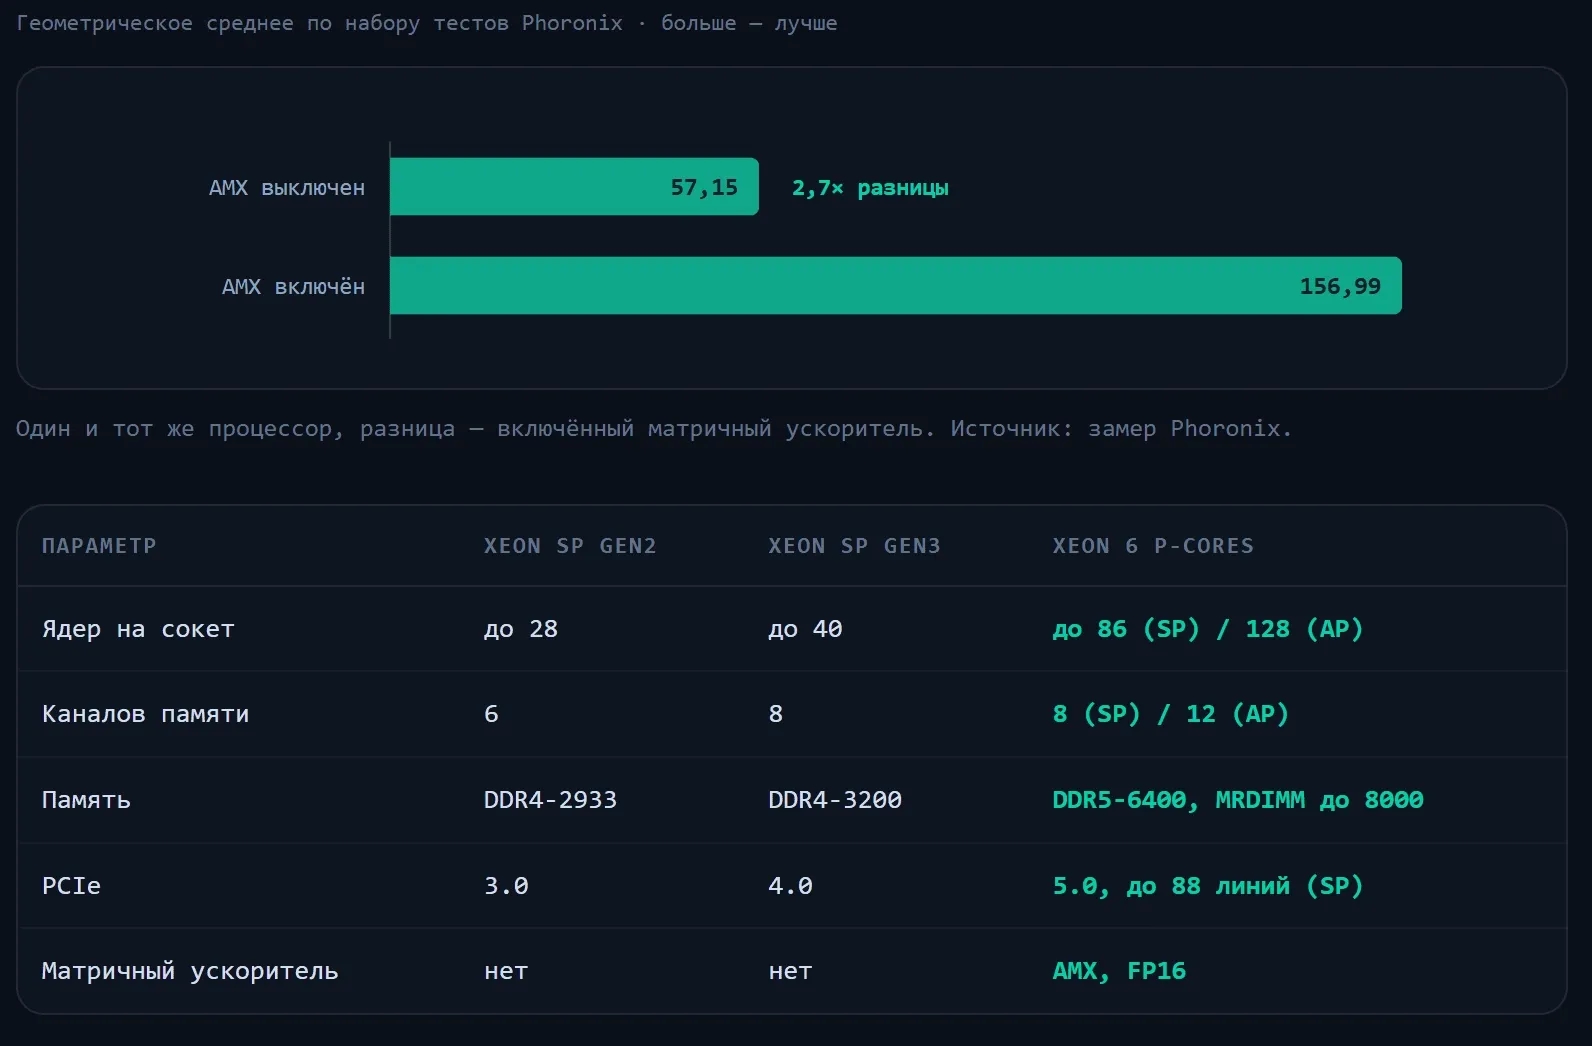
Practical implications: memory bandwidth has roughly doubled compared to Gen2, and inference for small models is limited by memory, not arithmetic.
Intel published benchmarks on a dual-socket system with Xeon 6767P processors—64 cores per socket, 128 cores total, four NUMA domains, and DDR5-6400 memory. The engine is vLLM 0.9.0 with prefix caching, running on Ubuntu 22.04 and RHEL 9.6, using the Sonnet dataset, with three runs per combination. The same model, four workload profiles—only the input and output ranges differ.
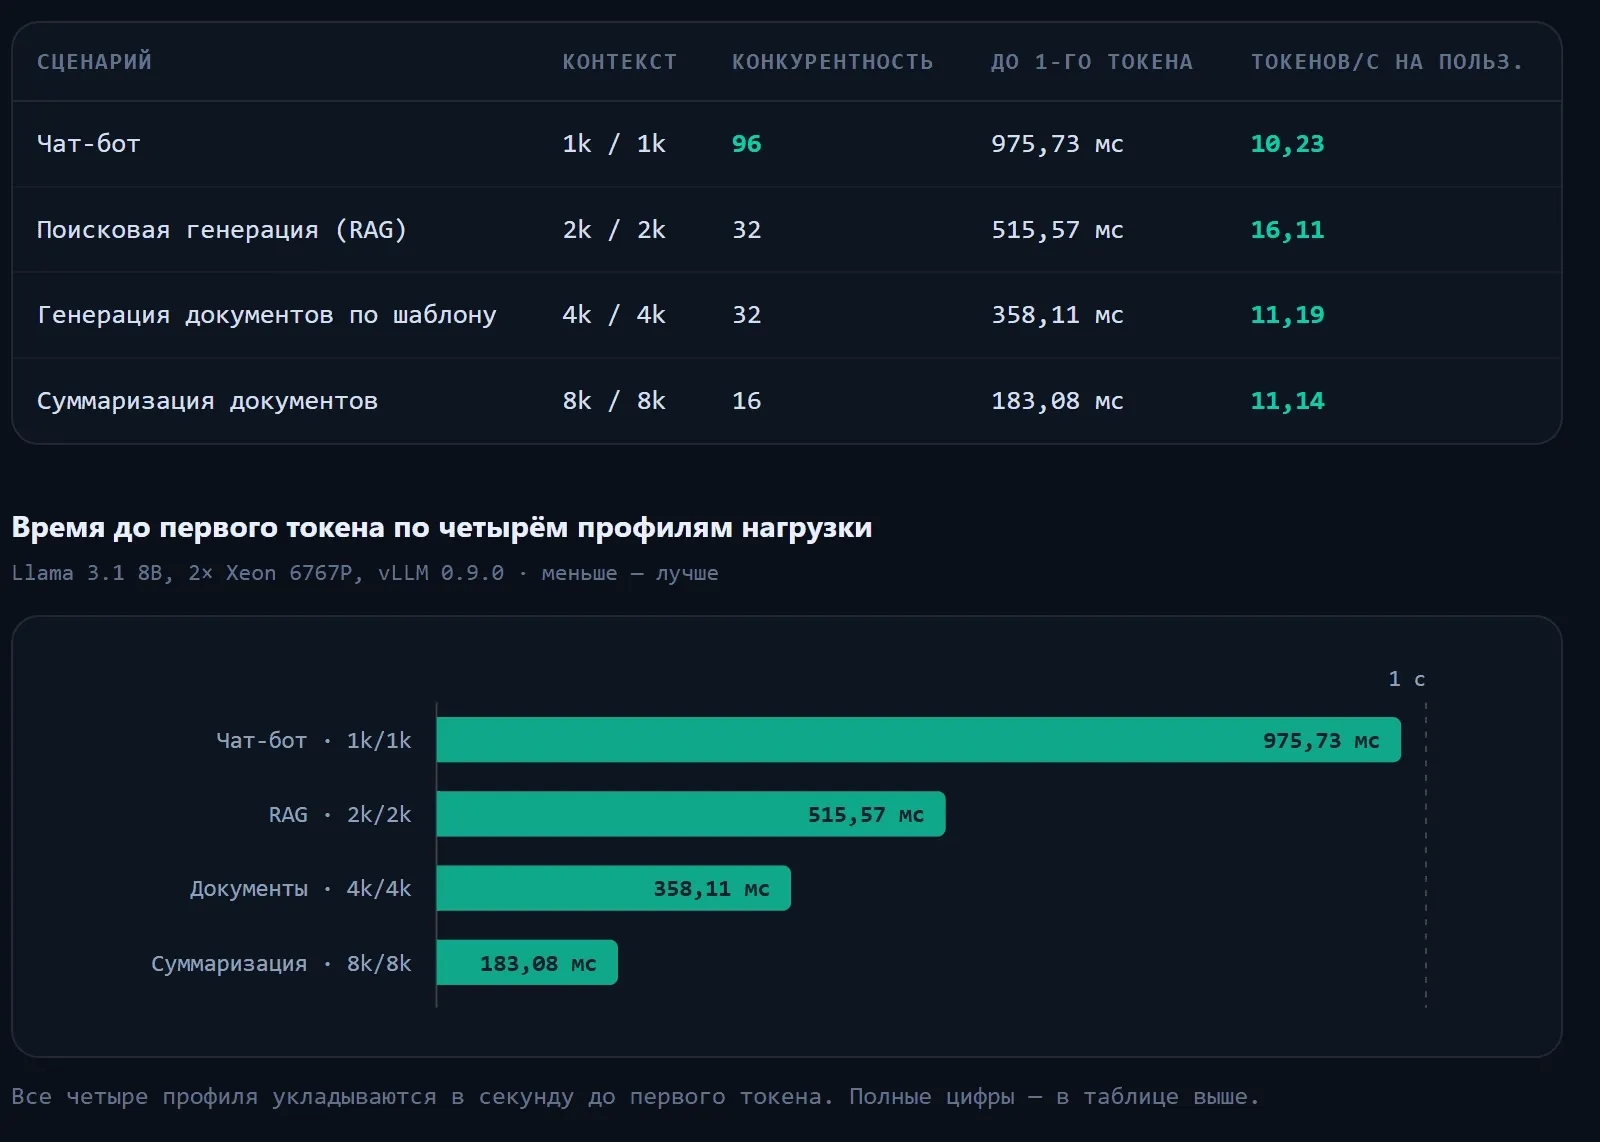
The benchmark for an acceptable user experience in generative interfaces is 10 tokens per second per user: this is faster than a human can read. All four profiles meet this benchmark, and the chat profile does so with nearly a hundred concurrent requests and a response time of less than a second.
The conversion to users is performed via a pipeline. A hundred concurrent requests to the engine equate to roughly a thousand users logged in via a browser or mobile app: requests reach the vLLM via a load balancer, an application server, and Kafka, which smooths out the flow. Plus, there’s the cache: in a narrow enterprise scenario, requests are highly repetitive, and the caching layer in front of the engine serves some of them without any computation at all—directly from the same server’s DDR5.
The map of enterprise scenarios that Intel has compiled based on its own experience is consistent across customers:
They all have one thing in common: an 8–11B-level model, dozens of concurrent queries, and the requirement to keep data internal. It is precisely this profile that runs comfortably on a CPU.
There’s no need to build a pipeline from scratch. Intel is a member of the OPEA consortium (Open Platform for Enterprise AI, a project of the LF AI & Data Foundation) and provides validated RAG pipelines: PDF parsing, loading into a vector database, metadata storage in MongoDB, context extraction, and transfer to vLLM. Deployment is via Docker or Kubernetes, including on top of OpenShift, Nutanix, and VMware.
Two practical architectural tips that will save you months of work down the road:
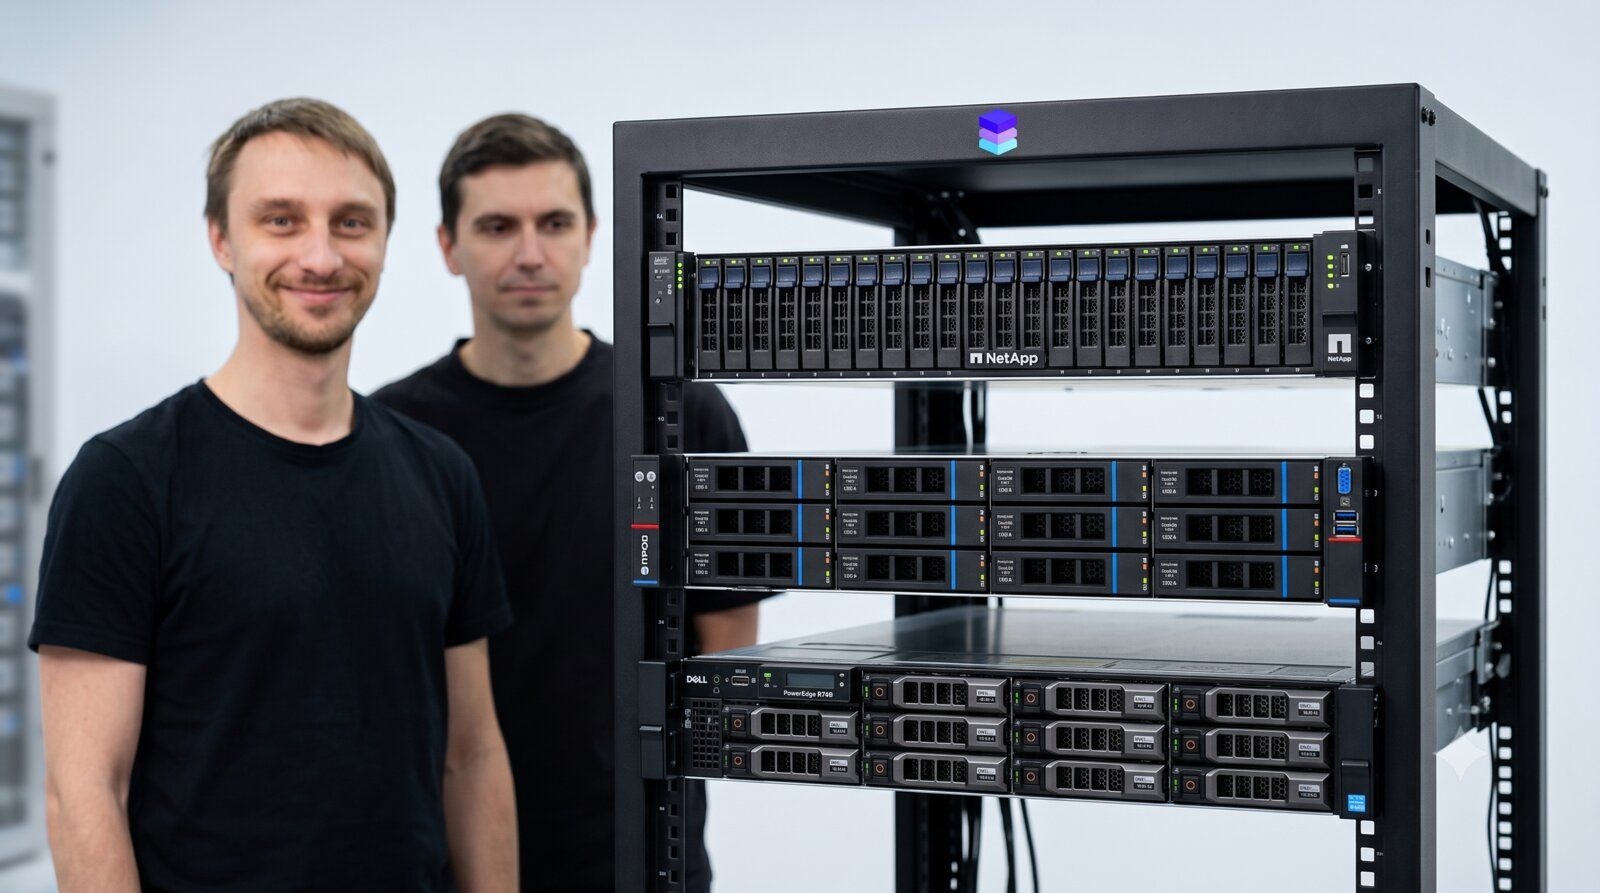
ITPOD-SL201-D12R-NV-G5 (center of the rack): 2U, 12 universal bays with front-panel hot-swap capability.
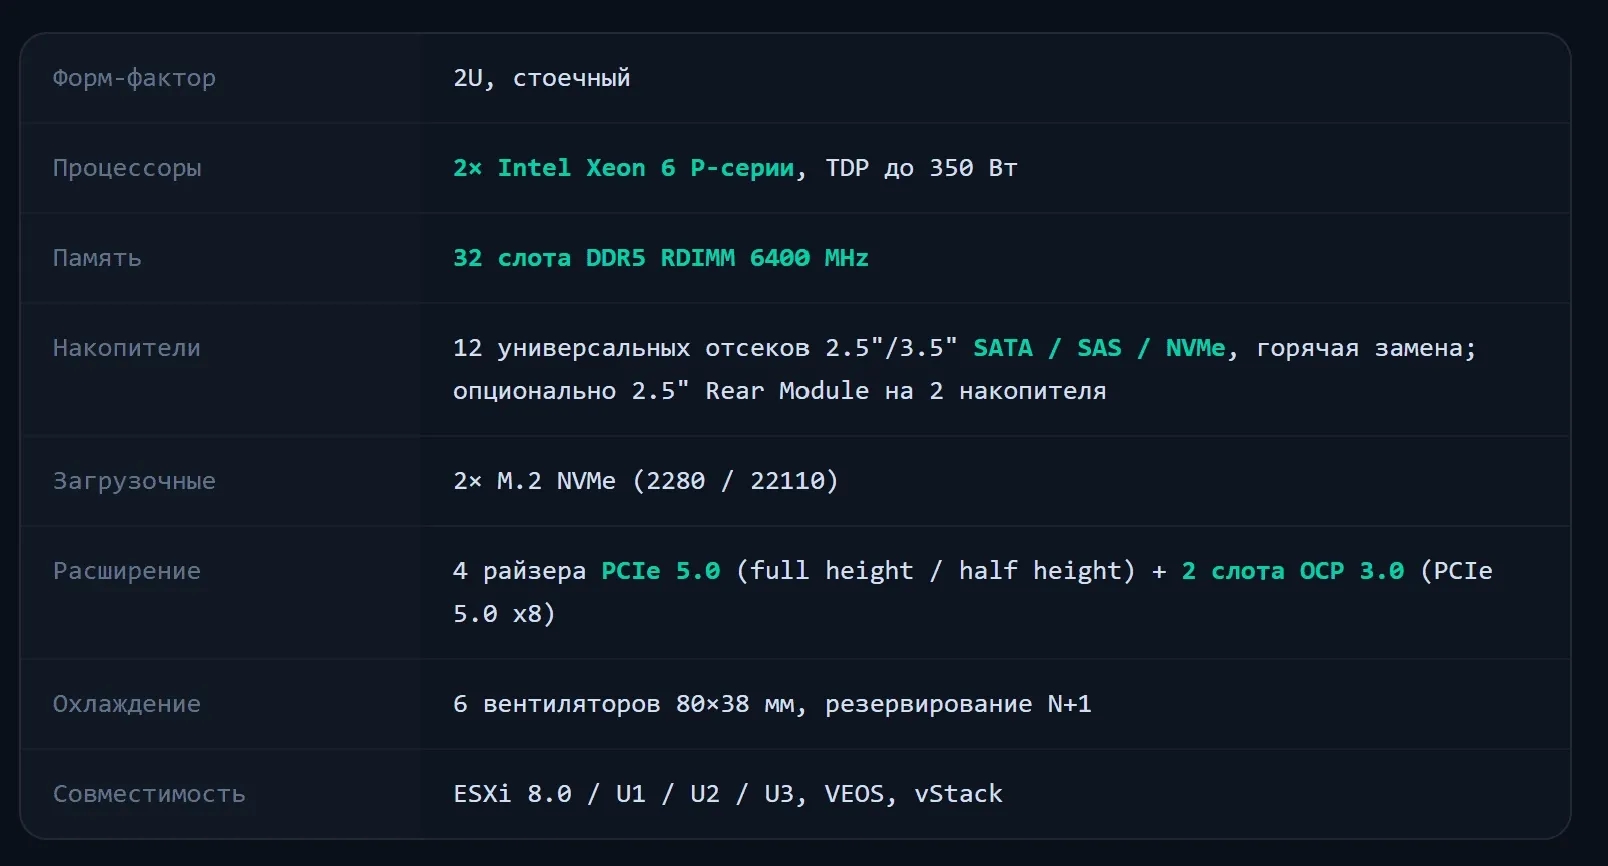
What’s important here specifically for the AI pipeline is the D12R-NV index, which denotes a universal backplane: the same twelve bays can accommodate both SATA/SAS and NVMe drives in any combination. The vector database requires NVMe, while document archives and backups use high-capacity SAS drives—and there’s no need to spread them across two servers. Two OCP 3.0 slots on PCIe 5.0 support a 25/100G network without using riser cards: those slots remain available for storage controllers or an accelerator, should one be needed later.
An engineering note on memory: 32 slots across two sockets equate to 8 channels × 2 modules per channel. The rated 6400 MT/s is guaranteed when one module per channel is installed (16 modules total). The second half of the slots is about capacity, not speed: at 2 DPC, the frequency drops. Inference is limited by memory bandwidth, so for AI workloads, we configure 16 larger modules by default rather than 32 smaller ones.
Engineering note on NUMA. Two Xeon 6 sockets equal four NUMA domains. Without proper vLLM pinning across domains, the figures from the table above cannot be replicated: the engine starts fetching weights via the inter-processor bus. This is a deployment configuration, and we set it up during the commissioning phase.
The threshold remains the same as it was a year ago; it has simply shifted. Models with 8–11B parameters run comfortably on a CPU in interactive scenarios with dozens of concurrent requests. Beyond this threshold lies the GPU:
For these tasks, we offer the AI/ML Computing series—4U chassis supporting up to eight accelerators. But starting a project with this series when the first use case is a knowledge-based chatbot means buying expensive HBM memory for a workload that’s limited by DDR5.
We’re taking several machines for remote testing and are ready to run not synthetic benchmarks on them, but your actual task: your documents, your query profile, and your model. The output will be metrics in the same format as in the table above: competitiveness, time to first token, and tokens per second per user.
Describe your use case: the scenario, model size, expected number of users, and data pipeline requirements. We’ll see if it fits on a Xeon 6, where the boundary with a GPU configuration lies, and which ITPOD build is needed for it. If it turns out that this isn’t the right server for you, we’ll let you know.
Email us, and we’ll put you on the list for a remote test run in August.
Servers
Servers
Servers